Monday, October 13, 2025

EasyDB Architecture Explained: Building Blocks of a Tiny Database

EasyDB Architecture Explained: Building Blocks of a Toy Database

This blog post explores the internal architecture of EasyDB, a lightweight educational database written in Java. We'll start with a high-level overview of modern database architecture and key algorithmic design choices, then walk through EasyDB's components across four areas: storage, MVCC & ACID, query execution, and indexing/query planning. Each section covers design trade-offs and includes source code examples.

Database Architecture Overview

A modern relational database typically consists of the following subsystems:

This blog post explores the internal architecture of EasyDB, a lightweight educational database written in Java. We'll start with a high-level overview of modern database architecture and key algorithmic design choices, then walk through EasyDB's components across four areas: storage, MVCC & ACID, query execution, and indexing/query planning. Each section covers design trade-offs and includes source code examples.

A modern relational database typically consists of the following subsystems:

  1. Storage Engine: Manages how data is physically laid out and persisted. The core challenge is balancing cost and throughput. For example, PostgreSQL uses 4KB pages because that size aligns well with physical disk block sizes and minimizes I/O overhead. The storage engine includes page formatting (e.g., slotted pages) to support transaction management, index and vacuum etc.

  2. Transaction Management: Ensures ACID (Atomicity, Consistency, Isolation, Durability) properties through concurrency control and logging.

  3. Query Processor: Parses SQL, plans execution, and runs logical operators using execution models like Volcano.

  4. Indexing and Optimizer: Supports fast data retrieval using index structures and selects efficient query plans.

Algorithm Comparison Across Core Areas

ComponentAlgorithmDescriptionProsCons
StorageTuple-based Layout and Vacuum supportClassic tuple based storageFast in-place CRUDNeeds Auto Vacuum to cleanup the zombie records
Null Bitmaps Compression to save spaceCompact format to save spacesExtra calculation and state managment
TransactionsMVCC with XMIN/XMAXSnapshot-based read isolationReaders don’t block writersOld versions need cleanup


Query ExecutionVolcano Iterator ModelOperators implement next() to fetch rowsMemory efficient, modularNo vectorization or parallelism
Rule-based PlanningUses indexes if availableSimple to implementNot cost-optimal
IndexingClustered B+ TreeSorted, balanced tree for equality/range queriesFast range scans, efficient searchSlower writes, not version-aware
Heuristic Plan SelectionChooses plans based on field/index availabilityEasy to understandNo cost-based decisions

With this context in mind, let's explore how EasyDB implements each of these components.

1. Database Storage

Overview: EasyDB persists data using slotted page storage and write-ahead logging, organized with in-memory buffer management.

Core Structures:

  • Tuple.java: Tuple header layout and version management.

  • PageImpl.java: Page structure and raw byte array management.

  • Stroage.java: Handles file reads/writes and page allocation.

Algorithms & Concepts:

  • Header Format: Tracks validity and size metadata for each record.

  • Null bitmaps: Bitmasks to track the null columns.

Pros:

  • Clear and efficient control over memory and I/O.

  • Easy to understand format.

Cons:

  • Manual memory management with potential for leaks.

  • No automatic eviction or LRU.

2. MVCC and ACID Guarantees

Overview: EasyDB uses Multi-Version Concurrency Control (MVCC) and a transaction table to enforce ACID semantics.

Core Structures:

  • TupleHeader.java: Transaction table and state tracking.

  • VersionManagerImpl.java: MVCC logic and isolation.

  • LockTable.java: Two-phase locking and deadlock detection.

Algorithms & Concepts:

  • XMIN/XMAX per record: Identifies creating and deleting transactions.

  • Visibility Rules: Based on commit status and transaction start time.

  • Undo Logging: Stores oldRaw in each DataItem for rollback.

Pros:

  • Snapshot isolation with non-blocking reads.

  • Rollback and recovery support with WAL and oldRaw.

Cons:

  • Manual version chain cleanup required.

  • Writers can still block due to locks.

Code Highlights:

public static boolean isVersionSkip(Transaction t, long xmin, long xmax) {
    return t.getLevel() == 3 && t.getXid() != xmin && xmax != 0;
}

Ensures repeatable read isolation by detecting version skips.

3. Query Engine

Overview: EasyDB implements a unified query processing pipeline that spans three key stages: parsing, planning, and execution. This modular flow is built on top of JSQLParser and operates using a Volcano-style iterator model to deliver results.

Parsing

EasyDB uses the external JSQLParser library to convert SQL strings into structured syntax trees. This parsing stage breaks down a query into its components—select fields, tables, conditions, and expressions—making it easier to reason about the query in subsequent steps.

Code Path:

  • TableManagerImpl.java – Handles SQL statement type dispatch.

  • Table.java – Extracts parsed clauses (e.g., WHERE conditions) and converts them into internal representations.

Example:

Statement stmt = CCJSqlParserUtil.parse(sql);

Planning

Once parsed, EasyDB builds a logical execution plan. This is a rule-based planner that chooses between index scans and full table scans based on available indexes and WHERE conditions.

Plan Strategies:

  • No index available: Full table scan.

  • Single index available: Index scan with optional post-filter.

  • Two indexes: Intersect or union results for AND/OR logic.

Code Path:

  • Table.parseWhere() – Translates conditions into index-friendly filters.

Example:

if (f1 != null && f2 != null) {
    uids.retainAll(uids2); // AND logic with index intersection
}

Execution

Execution is carried out through a simple iterator pipeline that mimics the Volcano model. Each query returns a list of candidate UIDs (record IDs), which are then read using MVCC filters and transformed into result rows.

Execution Flow:

  1. Iterate over candidate UIDs.

  2. Use VersionManager.read(xid, uid) to fetch visible records.

  3. Apply WHERE clause filters.

  4. Project selected fields.

Code Path:

  • Table.select() – Performs MVCC-based filtering and row materialization.

  • VersionManagerImpl.java – Controls record visibility.

Example:

for (Long uid : uids) {
    byte[] raw = versionManager.read(xid, uid);
    if (raw == null) continue;
    Map<String, Object> entry = parseEntry(raw);
    if (matchesWhere(entry)) result.add(entry);
}

Pros:

  • Modular and easy to extend.

  • Clear separation between parse, plan, and execute.

Cons:

  • No cost-based optimization.

  • No pipelining between operators or intermediate plan tree.

4. Indexing, Stats & Query Planning

Overview: EasyDB supports clustered B+ tree indexes and uses basic heuristics for query planning.

Core Structures:

  • BPlusTree.java: Tree operations and page structure.

  • Node.java: Leaf and internal node definitions.

  • Field.java: Index lookup and condition handling.

Algorithms & Concepts:

  • Clustered B+ Tree: Leaf nodes store data UIDs; inner nodes guide search.

  • Range Scan Support: Sibling pointers for fast traversal.

  • Rule-Based Plan Selection: Favor indexes over full scans.

Pros:

  • Fast equality and range lookups.

  • Efficient key ordering and storage.

Cons:

  • Indexes not versioned — may point to stale records.

  • No histogram-based cost estimates.

Code Highlights:

List<Long> uids = f1.search(res1.left, res1.right);

Uses B+ tree index to retrieve UIDs matching a range.


Final Thoughts

EasyDB (Java version) demonstrates many core components of database systems — from slotted pages and WAL to MVCC and B+ tree indexing. While simplified, it offers a clear and accessible path to understand database internals.

For more details, browse the EasyDB GitHub repository and try hacking on it yourself!

Sunday, May 25, 2025

Building a toy database from scratch with Cursor

As an experienced backend engineer, I have been trying to leverage Cursor to explore the potential of coding agent. The experiment (Build a toy database from scratch) is ranging from Dec 2024 to March 2025,  32 commits, and thousands of lines of code, here are the three lessons I learnt from it.

TLDR: Coding agent is a capable peer engineer you can leverage as every part of the SDLC, but intentionally.

#1 Context is key

Building a database from a high level can have different approaches, from the high level to the detailed implementation, each context could be different, feeding in right amount of context for the coding agent is critical. The engineer is capable at every part of system from architecture to coding, but you just need to treat him as a buddy to brainstorm, communicate, and think together.

At a high level, choose your high level mind first. Building a database could be relational, key-value, inverted search, document-based, or vertor-based etc. It is easy for the coding agent to generate a framework code for you, but you will need to determine which architecture style you would like to go with. In my case, I go with relational, and asked Cursor to stick to the postgres implementation by defining a cursor rule

At component level, try to setup a minimal structure to get started and iterate incrementally. A database is composed by storage, index, query, parser, execution, transaction, maintenance, admission control etc. It can easily be overwhelmed for the coding agent to copy other implementation and overwhelm your mind and project. Try to start small, I started with a memory-based storage, and then focusing on query engine, and index later. I had tried to go faster and let the coding agent do everything, but then I have to revert and take a step back, simply because the project is out-of-control.

At a detailed level, implementing a specific algorithm can have different styles, for example: the MVCC (multiple-version concurrency control) can have different way of implementation, try to brainstorm with the coding agent and think together which way is the best, and then choose to go with the path. For example, I brainstormed with the agent on Version Chain, but the version chain could be implemented at the tuple, or a separate data structure, but the original storage layer is better suited with the tuple level, it make the coding implementation easier. 

#2 Commit frequently

Working on large-scale and thinking intensive system is challenging, so does for the agent, The agent is easy to copy and understand the existing systems, but building a new system is always have some innovative aspect, and the agent is NOT you, and will not follow 100%. If the chance is right, the agent can help 10x your productvitiy, but it can also easily ruin your hard-working project. So, do backup, by commit frequently.

When I was firstly get started, I did not do it, and hard lesson is I have to restart on a big part of the project.

#3 Set boundary clearly

The toy database is built with Bazel 7, which has limited information on the internet, so whenever I asked it to fix a build, it always copy some instructions from the previous Bazel versions. So I have to specific the cursor rule to instruct the coding agent always use a Bazel 7 version, so it can reduce the chance that it is telling wrong answers.

On the coding and testing part, specific your coding style and testing framework you want to use and follow on. There are many different implementations to copy from, coding with intention.

Next Steps, it actually give me more fun for coding, and will try to build more toy systems with it.


Saturday, August 24, 2024

Do you happen run a release meeting?

Recently I joined a new company, was assigned to run a release meeting, after about three months on this journey, we have streamlined the process, and now, the structure is in place. I wish there had been some guidelines available when I first started on this endeavor. So, here I am, documenting and sharing my experiences and thoughts in an effort to provide some assistance to others.

Is Release Meeting a Gatekeeper ?

The first question is, what exactly is a "release meeting"? Is it akin to a gatekeeper, welcoming everyone and regulating the release of changes? This seems like an inappropriate and even offensive operation. But there must be a reason for its existence, right?

The rationale behind this process seems to be the presence of incident, that are released without undergoing the necessary checks or considerations before being deployed to production. This may be the result of several factors:

  • Knowledge Silos: The current system is a large-scale complex service, with over 30 engineers working on it simultaneously, making it challenging for everyone to be on the same page.

  • Reorganizations: Due to reorgs, many team members with contextual knowledge have left, and the existing practices have been lost.

  • Reviewer Culture: As part of the reorgs, new engineers have been hired, and the knowledge or context has been lost. There are not as many experienced reviewers as before.

  • New stack: We migrated from Java to Kotlin, Cassandra to PostgresSql, introduced new proxy service, it takes times and knowledge for it to mature.

  • Urgency of Delivery: Fast delivery is expected as part of the performance review process, but not necessarily the quality of the changes. Engineers are focused on quick delivery.

  • Tooling: We have transitioned from micro-repo to mono-repo, and the practices of default reviewer, local build, and testing are no longer as straightforward. There is a gap in tooling.

Closing these gaps in a short timeframe (say a quarter or two) is an impossible task, and introducing a gate between development and production is an approach to bridge this gap.

Quality at Speed or Quality Over Speed 🙇?

As an industry leader in the space, we aim to move as fast as possible while maintaining quality. At Atlassian, there are practices in place to achieve quality at speed. But what happens when speed does not meet the quality bar, especially when you inherit a business with a history of reorgs?

Firstly, you will need to define the quality bar for yourself. The bar varies at different stages of the business. It is expected for a startup to quickly try and fail and get the first MVP out the door. However, it does not make sense for an established platform to build services like startups and to try and fail. Take some time to understand the legacy barand incorporate your own understanding and thinking

Secondly, you will need buy-ins. Seek advice from passionate engineers , empower engineers to create code review checks and support engineers as role models to showcase the right behavior.

Thirdly, apply changes using the bar gradually and incrementally. I still remember the first time I pushed back a change without testing. The angry voices passed through the internet cable, and it surprised me. After three months, I wouldn't expect any engineer to come to the release and push changes to production without testing. It has become the new normal. A few things I found useful:

  • Conduct a survey💬, the release meeting survey helped me understand what the bottom line is and the potential pushbacks. The code review survey legitimized the change since there was a demand for it.

  • Review changes that did not go through the release meeting🚪. Release meeting is a mandatory process, enforced by humans. It is a cultural thing that requires communication. Observe the changes that did not go through, ask the reasons, and socialize it to help formalize the culture.

  • Empathy:heart:. It is easy to say no from an approver's perspective, but we all want to move fast. As a team, wearing the other person’s shoes to make the engineer succeed matters.

Fourthly, prioritize quality over speed when speed takes precedence over quality. This requires a mindset change and lessons for everyone. We found it useful to take incidents as educational opportunities. when there is a incident, on the second day, the first thing to do is review and assign the following mitigation action items.

Lastly and importantly, account reliability when planning. We are fortunate to have the support of TPM(Technical Program Manager) , engineering managers. By sharing this common understanding, we can assist the leaders in creating sensible plans that ensure quality and reliability are thoroughly considered as part of the planning process, including readiness review, progress rollout plan, and rollback procedure. 

The Release Train :bullettrain_side:

A release has an owner, frequency, and speed, and it varies from team to team. Given the nature of perms, we find that daily releases, service ownership, risk classification, following a progressive rollout, and ordering are helpful.

Release frequency varies from monthly, weekly, to bi-daily, or daily basis. The system is operated by a large team with over 30 engineers working together every day. There are about 6 changes that need to be released to production. These changes vary from VLUN fixes, service onboarding, feature changes, to major production changes. Piling up changes for a week, actually more than 30 changes, makes it hard to evaluate, as all the critical, high, and low-risk changes need to go together, making it difficult for both the reviewer and code owner.

The release typically goes through an automatic release pipeline, with automatic checkpoints in between. However, there are issues and misses as part of the process. It is important to assign the change owner to monitor the changes in staging and region by region. Having an on-call person to oversee every change is humanly impossible, so the owner must be accountable and take the time as part of the planning.

When there is a major change in one day, we classify that day as special. For example, the event release day. We hold other changes to focus on it. This practice has been applied multiple times as part of the one critical service migration, staging db change, and others.

We also classify critical change packages so that only specific owners can change them. the main focus was on reader migration, so we changed the owners to only reader owners..

Sometimes, there are deployment orderings between releases within a day. Identifying those and asking when to release, who to coordinate, and what to verify helps engineers streamline between the changes and reduce the risks. Within one deployment, leveraging the progressive rollout guideline justifies the timeline pressure and empowers the reviewer to push back the dates.

What's Next ?

Now that we have established a structure and mindset change within perms, the following steps are being taken:

  • Grant more freedom, starting from low-risk changes. Not every change is high risk, and after verifying many times that the change is safe, we will classify them and trust the existing checkpoints.

  • Empower reviewers. Software is built by engineers with culture, practices, and knowledge, all of which are driven by human. Coaching is the path to cultivating programmatic engineers and constructing resilient systems, and code review is one of the best ways.

  • Bridge the gaps within the system, particularly in design, development, testing, monitoring, and alerting. Embracing systems over human intervention is key to minimizing the occurrence of "bitter lessons" such as this.

Sunday, February 25, 2024

Platform engineering - How does it work?


Platform Engineering: How does it work

Introduction

Platform engineering is a Top Gartner 2023 IT Trend. There are different concepts in the industry, but how can these concepts and products help an enterprise?

This article will discuss platform engineering from an enterprise perspective.

What does a tech organization need?

Digital transformation has changed enterprises. Every enterprise needs IT investments. As the enterprise grows, the Tech department also grows. To operate the Tech teams efficiently, just like an enterprise requires ERPs and CRMs, the Tech team needs specified tooling to achieve operational efficiency. This is now called DevOps, but there is often a disconnect.

Tech is built by people, for people. People are humans and cannot be 100% available like a machine. To achieve the desired quality, efficiency, and cost, a systematic approach is needed to cover every aspect and work well with PM, Dev, Test, and Ops engineers.

Amazon, for example, uses Dev to cover Dev, Test, and Ops engineers' roles, sometimes the PM role as well, and learns from that. Then, it applies the learning into the product itself to close the loop. Internally, Amazon has a strong infrastructure and Tools platform to cover for the engineers, so the engineers can focus on the actual work for each, rather than environment settings, permission management, host replacement, etc.

Google built Borg to achieve consistency in cluster management and improve cluster utilization to reduce costs. Google also invented the concept of SRE and built SRE engineering to focus more on continuous delivery, monitoring, etc. Based on the Tools and Infrastructure internally, they built and open-sourced Kubernetes. Kubernetes has gained tremendous popularity across the industry and changed Tech.

Amazon and Google are the whales, but you can also see examples from Netflix, Airbnb, Uber, etc.

Why does a tech organization need platform engineering?

The public cloud market share is expected to be 500 Billion in 2022 and 600 Billion in 2023(according to Gartner report). While it has gained tremendous popularity and redefined the IT industry, it has also created a tremendous challenge for DevOps. The infrastructure and tools used before have changed to Multi-cloud. The complexity has caused the developer efficiency to be lower, cost to increase, and quality to vary.

Platform engineering simplifies the build experience of new products. When a company is young and growing at its baby stage, it keeps trying to find a product-market-fit. At the growing stage, it matches multiple use cases and customers adopt it with a similar expectation on latency, performance, scalability, and experience. One way to achieve this is to use the same engineers or the engineers who have done this before. Another way is to bake the engineering experiences into tools and platforms, so products gain the learnings easily.

Platform engineering simplifies internal governance. Software organizations are product-lines with innovation. They innovate constantly and build different product lines. The dynamism from a product perspective is encouraged. The governance requirements typically land specifically in one organization, called platform, compliance, and as of engineering DevOps, it is now called platform engineering, with an emphasis on being platform-driven, but still focusing on the engineering metrics like requirement delivery time, deployment failure rate, software bug count, etc.

Platform engineering Concepts

The software industry is good at innovating new concepts, but they all have a purpose and history.

The Internal Developer Portal (IDP) is to build a standardized portal experience. With the emergence of micro frontend architecture, it has made it easier to build templatized and decoupled frontend architecture. Netflix shared their experience regarding Paved Road, and Spotify open-sourced backstage, which matched the enterprise internal websites demand.

Infrastructure focuses on operations, but the practices vary for company type. For the cloud companies, it means the hardware supply chain, standardization, virtualization, cluster management, etc. For the companies that rely on the cloud, it means to provide simplified, standardized, and secure access. Examples include Kubernetes and their variations, infrastructure-as-code, etc.

Productivity Tools focus on engineering output, with a focus on code lines output, code review count. Sometimes it also provides release tools, for example, Bazel, compiler tools, and software deployment tools. It embeds the software best practices standards within the tool to accelerate the development process.

How does it work for an enterprise

Enterprises focus on the quality, speed, and cost aspects of engineering.

On the quality part, the productivity tools embed the software standards. For example, Google used Code Review Certifier to review the code changes, with the tooling enforcing that checklist. The industry has multiple practices including LORE, SPACE to focus on different metrics, but the goal is the same, and the method will vary.

On the cost front, it is either the people or infrastructure cost. With a centralized infrastructure organization, it has the ability to control the infra cost, but to not impact the businesses, there is typically a negotiation process and a top-down OKR to drive it.

On the speed of innovation, the productivity tools in Google invented Bazel to accelerate the build speed. Netflix invented Spinnaker to simplify the deployment process, and Today there are AI tools to help generate code and tests.

In the end, this space is not new, but the mindset has evolved time-to-time. With the new AI innovation in the space, we are likely to see more.

Monday, January 15, 2024

DevOps Transformation at Tencent Infrastructure Services

 To memorize the two year journey from 2021 to 2023.

Summary

Tencent's Infrastructure Services (TIS) owns a critical part of the Chinese internet (such as WeChat). As time flies, operating the business becomes more painful using the legacy embedded model. To transform the operations, we built the internal DevOps platform (EasyCloud) to solve the challenge using software.


TIS architecture is one of the most technically complex parts across the company. It has built core COS (similar to S3), CBS (similar to EBS), and CDN for the whole Tencent business. TIS's business has both a public and private cloud. The public cloud runs a partnership with Tencent Cloud with a focus on the dataplane side.


Both the technical and business complexity have posed pressure on both engineering and DevOps, leading to the pains of efficiency. The leaders of the business want to make a change.


Over the past two years, TIS built its internal EasyCloud to unify and automate the operations. At the end of the 2-year journey, the VP said, “The things I did not see change in the last 10 years, I see a change in the last 2 years.”

Legacy architecture and challenges 

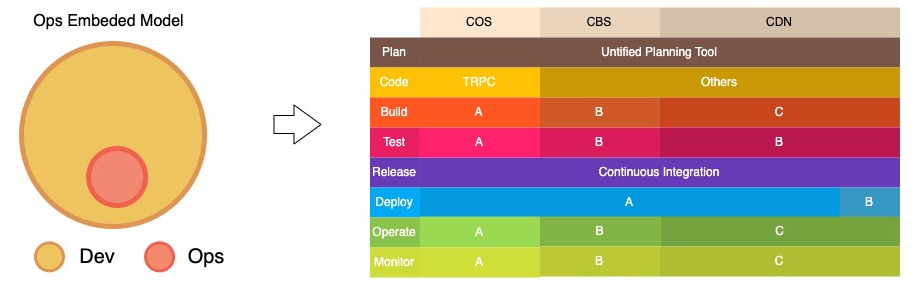
TIS started as a storage service, and the complexity of architecture, coupled with rapid growth, required Ops engineers to collaborate deeply. To support this growth, the ops teams were embedded into the storage business, a strategy that proved to work well.


Figure 1: Legacy Ops Embedded Model empowered the growth also leads to tooling silos and fragmentation.


During more than 15 years of growth, as TIS scaled its business, the embedded model scaled accordingly. As a result, the overall business faced the following challenges:


  • A 6:1 dev to ops ratio: The public cloud business operations demanded a higher release frequency, a larger customer base, and a 10x increase in zone-based geolocations. Due to the current fragmented tooling and human-driven operational model, more business operations required more ops engineers.

  • 30% deployment failure rate: The deployment best practices were tribal knowledge held by experienced subject matter experts due to the tooling fragmentation. A new Ops engineer and a complex deployment could easily lead to deployment failure.

  • Low deployment standard parity: The continuous deployment platform had been rebuilt four times, and there were three deployment standards released before. During a customer conversation, one customer asked a question: “When did the deployment standard actually land consistently?”

Current Architecture

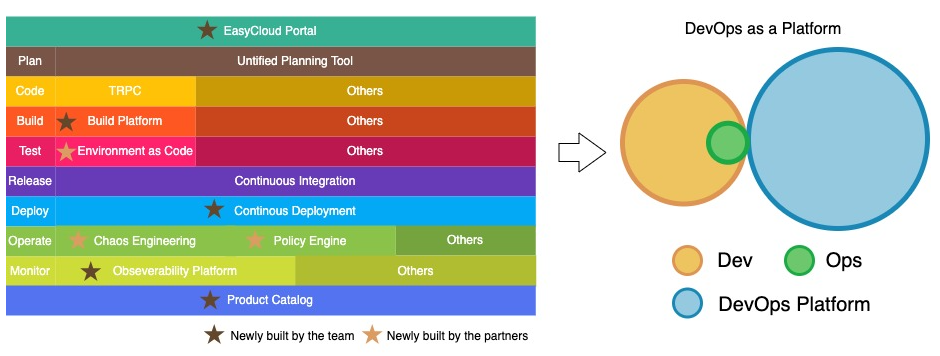
We achieved a 10:1 engineering to ops ratio by building the EasyCloud platform. This platform allowed us to build a suite of services and an ecosystem to automate deployment, chaos management, policy enforcement, and more. Enabled ops model transformation. 

Figure 2: EasyCloud enables an automated operating standard across businesses, transforming the operating model.


  • The Product Catalog and EasyCloud Portal lay the foundation for the EasyCloud ecosystem, facilitating transformation. The EasyCloud Portal serves as a unified entry point, offering insights and tools for daily use.

  • The Continuous Deployment Platform introduces a new CD platform with an embedded deployment standard and a pluggable architecture to execute deployment workflows at scale.

  • The Ecosystem and other platform services, such as Chaos Engineering, are built from day 1 based on the product catalog. As the platform proves successful, we continue to build more platforms, enhancing business efficiency, including observability and build platform.

Product Catalog & EasyCloud Portal

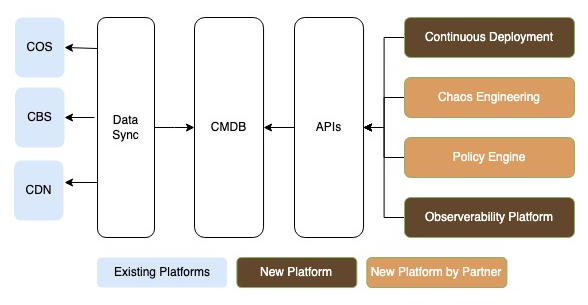
The Product Catalog (PC) constructs a tag-based Configuration Management Database (CMDB) for approximately 5 million instances worldwide. It establishes a unified and modernized view for all business operations. Engineers with over 5 years of experience in the field within the business have expressed that 'it has achieved what they dreamed about before.

Figure 3: Product catalog synchronizes data from existing systems and builds a foundation to enable an ecosystem.


Millions of instances of data synchronization. The TIS business had integrated the cluster and application launching process deeply into its own systems. The synchronization incrementally syncs the data (application, instance, and tags, etc.) at scale, builds appropriate indexes, and performs anti-entropy for data accuracy.


The CMDB is a tag-based service. It has built the batch and dynamic tag-based query with pagination to support legacy wildcard query use cases. The CMDB separates the primary and backup, that the primary is for write and backup for read.

Continuous Deployment 

Continuous Deployment (CD) deploys to millions of instances globally for both the public cloud and private cloud. A modern-tool-based deployment improvement has accelerated the deployment success rate to one quarter per business, three times faster than AWS.

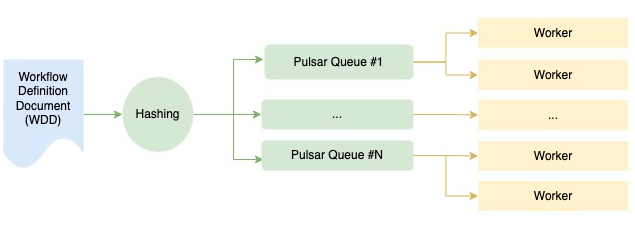
Figure 4: Continuous deployment empowers the standardization and flexibility at scale.


For the new CD, it enabled 100% deployment standard parity. The Workflow Definition Document (WDD) defines a standardized schema and builds 34 default workflow step execution plugins to support blue/green deployment, approval & notification, staggered deployment etc. It minimizes the deployment standard parity cost, with benefits on ease of use and scalability.


70% to 100% deployment success rate improvement. 

  • 6% reduction in system failures. The core of the CD is a workflow execution service that builds workflow allocation, idempotency, isolation, and delay tolerance to dramatically reduce service-related failures.

  • 10% reduction in failures. The standardization of the instance deployment template and improved failure handling both reduce and tolerate partial instance failures. The flexible workflow orchestration supports tag-based arrangements to enable use cases like hardware-type-based blue-green deployment.

  • 8% reduction in human errors. The new CD supports Subject-Matter-Experts (SME) to embed their experiences into the system. They are empowered to define their own standards, enabling any operator to operate safely without breaking the deployment.

  • 4% enforcement of quality checks. The system utilizes the PC to unify the data from CI and checks testing and version information as mandatory. It also enforces a double deployment check process (both the OP Leader and Dev Leader), the streamlined process leads to stable expectation on deployment.


4.8 out of 5 satisfaction. On the ease-of-use side, the WDD enables a flexible UI-driven orchestration, with a 200 ms latency at p99. On the system reliability side, the powerful execution engine provides control to pause and resume reliably. The overall service now boasts a 99.95% availability compared to 95% before. The simplified experience and dedicated on-call schedule contribute to a superior support experience. Requirements and feature requests are managed using our sprint and bi-weekly release process, providing a predictable expectation.

Ecosystem & Other platforms

As the CD proved to be successful, when given a chance, more systems were rewritten to build on top of the platform from day 1. Chaos engineering leverages the PC to perform scoped operations based on instance tags. The Policy engine service leverages PC to control the pace of scanning the operational environment to ensure production is safe.


The observability platform builds a unified metrics and event store to provide an application-centric and unified view to check the application health, handling petabytes of monitoring data per day. The build platform utilizes Bazel to offer an incremental build experience, with customized support for security and integration of the ecosystem.


Sunday, June 19, 2022

Transform an existing architecture - 6 - define and transform culture

 Define and transform culture

This blog is part of the series "Transform a large-scale architecture guide", see:


Why Define a Culture?

Culture guides the daily behaviors of a team, recognizes and rewards people, identifies great, good, and bad behavior, creates an environment, and defines autonomy. A good cultural environment is necessary for the team to scale and repeat success. Defining culture guidelines also defines the rewarding and recognition system. The right leaders will naturally emerge based on culture, leading the product, technology, and people to success.

A culture that cannot meet the growth of the industry or customer requirements will eventually harm the company. Complaints like being unable to recognize talented people, reward heroes, or prioritize self-interest over customers will eventually be sorted out by competition.

What is Culture?

Culture is a set of habits that people understand and follow well. For example, customer success is a culture, and the team's focus should be on customer success. 

Good behavior that creates customer success creates a habit/culture. A single habit cannot guide all behaviors. 

Customer success itself defines the guiding principles for work, but other important things may be overlooked. For example, a platform team needs to be simple and consistent. Simple means the platform API should be designed consistency for easy understanding. The concept across the platform should be consistent so that customers don't need to think twice. 

Culture defines the hiring, promotion, rewarding system, and guiding principles. Amazon specifically asks and trains people to use them in various documents. My team uses this for hiring, recognition, and promotion.

Define Culture

The first 20 people hired define culture. Culture is not obvious in the first month of running a business. It becomes more and more obvious when interacting with various stakeholders and customers.

The founder of the team defines the culture by hiring the first 20 people. It wasn't clear to me when I started hiring, but all the people hired reflect the founder's values and instincts.

The right culture makes customers and businesses happy. Identify the early stage successes and formalize them. For example:

  • Customer success: Customer success generates NPS, promoting and scaling business success.
  • Simple and Consistent: Simple interfaces and consistent behavior and APIs simplify the customer onboarding process and make internal and external team communication easier.
  • Open Collaboration: In a 2B business environment with many dependencies, finding opportunities to collaborate helps deliver requirements easier and simplifies communication upward or externally.
  • Data-Driven and Geek Spirit: Products are built by engineers. Good quality systems are data-driven. Engineers are hackers and are not afraid of technical issues. They always find ways to improve the systems.

Transform Existing Culture

80% of behavior is already decided when a person is hired. The existing people have already adopted a culture, so culture transformation is hard and needs to be done in phases.

  1. Hire the right people. Hire according to the founder's spirit, identify and decide across the process to ensure the right people are hired. It is a hard process. Interviewing 10 people may generate one candidate, and the market is also competitive. Get help from HR, hire through personal leads, and hire through friends.
  2. Promote the right people. With the vision and products defined earlier, promote the right people with the right behavior. The old behavior that does not make the business successful should be discussed during 1:1s with serious outcomes. Promote and reward the right people with the right behavior.
  3. Find positions for people with inappropriate behavior. Talk with peers and leaders to arrange open positions for them. For example, one Ops Engineer we worked with moved to another Ops team and was promoted to a leader because his behavior matched perfectly as an Ops engineer.
  4. Formalize culture and guide through hiring, promotion, and recognition. Communicate with leaders and team members to build a transparent working environment to help everybody be on the same page.

Transforming an existing culture is challenging since there are many connections in between. Start with a commonly understood vision, create as many allies as possible, and then transform with strength.


Monday, May 2, 2022

Transform a large-scale architecture - 5 - execution and delivery


Execution and Delivery


This blog is part of the series "Transform a large-scale architecture guide", see:


Ownership

Dividing a product into different milestones and executing them may seem like a straightforward approach, but it is a common pitfall. It is more important to have the right people with ownership to execute than the milestones themselves.

Recognizing the right people with ownership starts with trust in project/feature delivery. If the owner has a track record of on-time delivery and quality attributes, that person can be used as a role model to create an ownership culture. This may be the single most important thing for execution.

The ownership team culture is not easy to build, and project delivery should start from zero trust first. It should improve by tracking details end-to-end, building trust step-by-step, and then building momentum.

Communication

Conceptual and high-level designs set the direction for product delivery, but they need to be divided into different components. Each component will require collaboration among the APIs, UIs, and customer feedback. Things will evolve, and the product and people will need to change. What was designed at the beginning may not be exactly the same as the initial design.

The gap comes from communication. One-way communication is bad. Two-way communication and group communication are important. As an architect, fostering communication is vital to success.

Communication has style and content challenges. Documenting as many details as possible helps to bridge the gap. Take the time to write them down, as clearly and visually as possible. That document can be passed along from the beginning to the end, and it will help bring more context along the way. Sometimes things change, and documents become outdated, but the high-level design should still be the same. Key principles should last. Try to document key changes as appendices to the original design.

Communication is not only about high-level/detailed level design. It is also about code communication, which is the code-review process. Equal communication and bringing people along in the process help people learn and create programmatic programmers.

Fostering communication in a professional way and bringing people along the way creates an equal way of communicating. All the team needs is to create a fantastic product to help customers succeed. So, put personal ego aside and let's collaborate!

Meetings

As in Lean, Plan-Do-Check-Act is a four-step process for execution. For product development, once the initial design is settled, divide it into different iterations for execution.

Plan: Sprint planning is about setting the right expectations on task quality. Design, coding, and testing should meet the expectation. The planning should consider vacation time, holidays, release time, dependencies, etc. The planning should be from bottom-up and top-down. Bottom-up as for time estimation, top-down as for priority and definition.

Check: Review, testing, and feedback from customers can serve as checkpoints. During the development process, different checkpoints can be made, such as design review, code review, testing, and feedback. Finding feedback earlier benefits the product and the customers more.

Act: Retrospective or private communication can serve as action items. Retrospective is for team communication to have an open forum for discussing and improving as a whole. Private communication is for personal advice such as feedback, time management, quality issues, and performance evaluation.

Keeping Focus

Focus is about saying no. Different types of distractions during product development include production issues, bug tracking, escalations, and chaotic communications.

Production issues unfortunately affect the team's performance since customers come first. But capping that into a single person or half person helps. Find an engineer who is good at dealing with those and can also deliver. During sprint planning, consider that. During performance review, also account for that.

Bug tracking comes with a priority. High-risk priority should still need to be considered. During sprint planning, create another lane for that. Account for delivery and timeline schedule.

Escalations come from production issues and bug tracking. If they are not managed properly, they surely come with an escalation. Customer service is the first to calm down the customers. Communicate with direct timeline and schedule. Customers typically can resonate.

Chaotic communications should be delegated to one proper person. That person handles all the private communications and then optimizes by knowledge base, bots, etc.


[Joy]License Plate Pattern Recognition

1. Background and Goals Build a joy license plate character recognition system as a vehicle for  learning how the Softmax classifier works ....